


Vellum Went From LLMOps Platform to Personal AI Assistant — So Who Is It Actually For?
An MIT-licensed assistant with unusually serious memory engineering, from a company that used to sell evaluation tooling to AI teams — and a credit meter you need to understand before you commit.
📋 Table of Contents
Our Vellum review 2026 score is 7.65 out of 10. Vellum today is an open-source personal AI assistant with a layered memory system, apps on Mac, Windows, iOS and Android, and channels that include Slack, Telegram, email and voice. The engineering is more thoughtful than most assistants we have read about. The billing model is the part that asks the most of you.
If you know the name from somewhere else, you probably know the earlier Vellum: a workflow builder and evaluation platform for teams shipping LLM features, backed by Y Combinator and a $20 million Series A in July 2025. Same company, different front door. As of October 2026, the homepage, pricing page and main docs sell the personal assistant, and the older platform lives on in separate developer documentation. That shift matters for anyone comparing it to coding agents like Devin, because Vellum is no longer trying to be one. It is closer to a persistent teammate that happens to be able to write code.

What Vellum Actually Does
Layered memory that consolidates itself
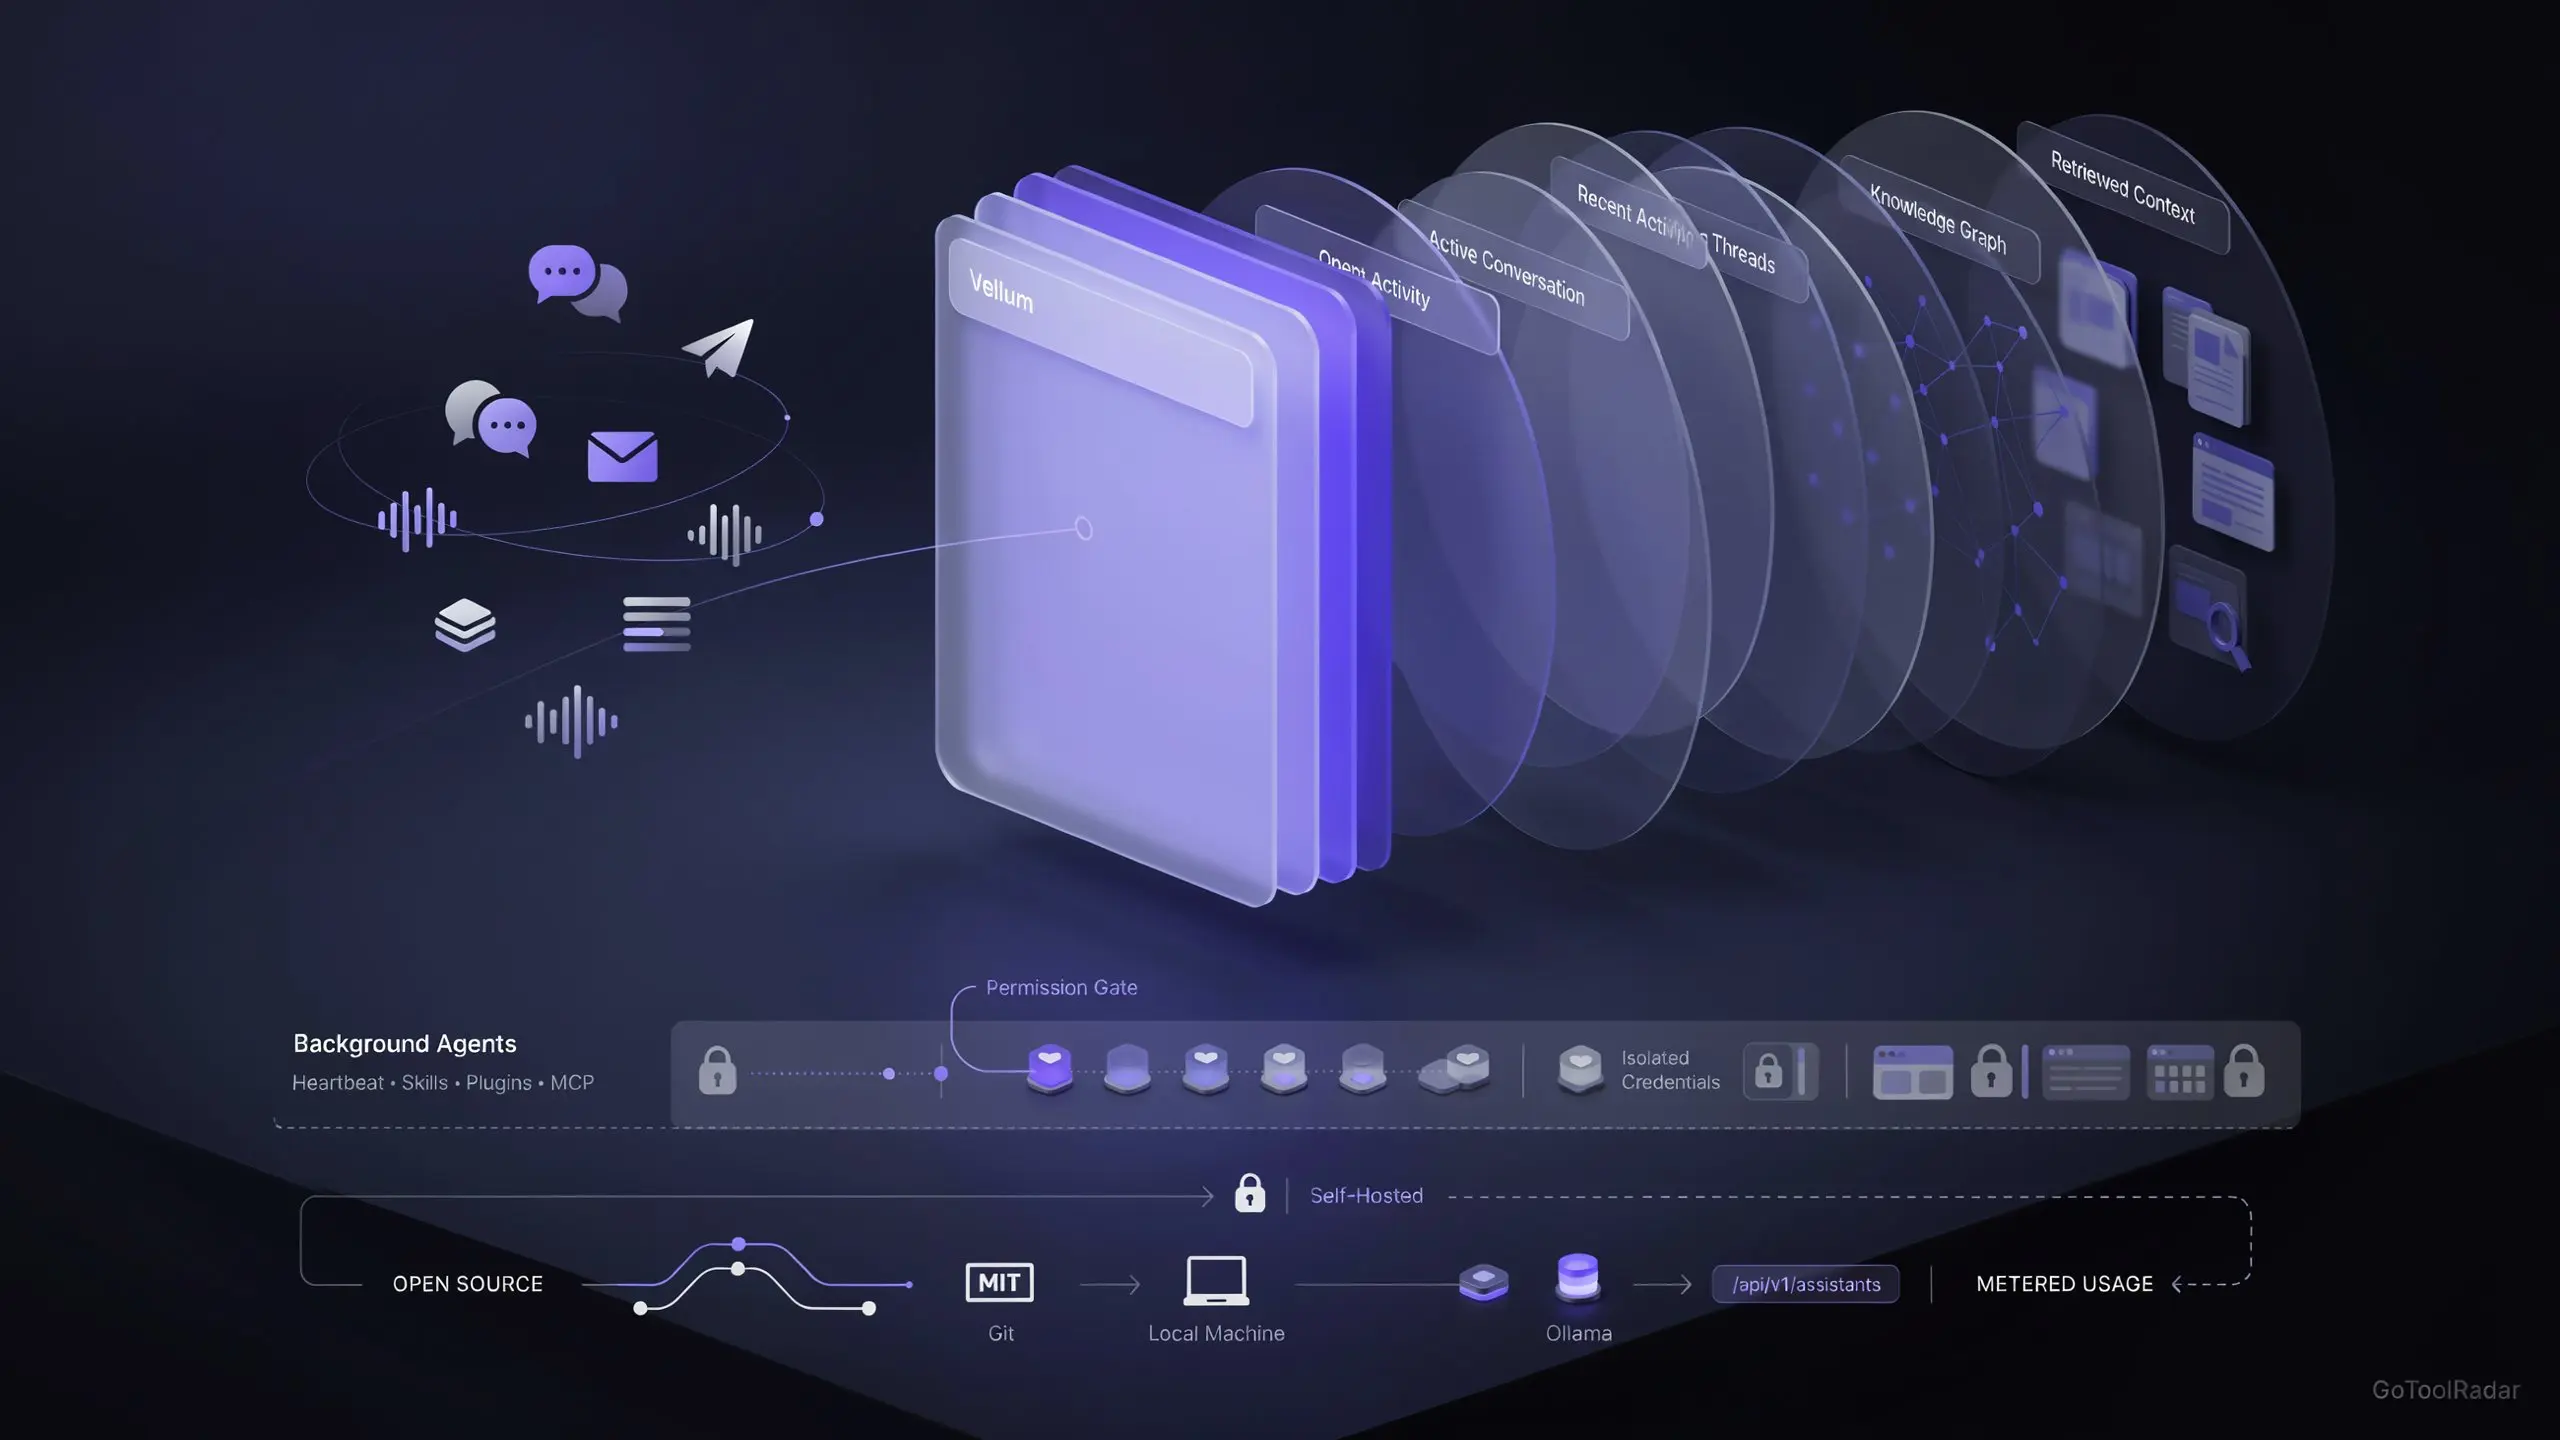
Four small files are loaded into every conversation: essentials, open threads, recent activity and a raw buffer. Behind them sits a knowledge graph of concept pages retrieved with a mix of keyword and vector search. A consolidation pass runs every four hours to decide what gets filed, merged or discarded, and corrections you make are fast-tracked into the always-loaded layer. Release notes say the current version retrieves individual sections of a page rather than whole pages, and the repository describes eight memory types. It is the clearest attempt we have seen to solve the problem we covered in why your AI forgets everything after every chat.
One assistant, many surfaces
Native apps for Mac, Windows, iOS and Android, a web app, live voice, its own email address on higher plans, and messaging channels including Slack, Telegram and Discord. Every channel shares the same memory, so a thread started in Slack can continue on your phone.
Proactive by design
A scheduled "heartbeat" has the assistant re-read its notes, look for anything unfinished or due, and message you if something needs attention. Independent work can be handed to background subagents that act as researcher, builder or advisor. Useful, and also the source of most background credit spend, which we get to below.
Voice and an on-screen companion
Voice mode went live in July 2026. On the desktop, a floating companion can see a window or tab you share, point at controls by name, and draw on screen while you talk. Vellum's newest product page, "Ambient," adds hold-to-dictate and double-press-to-delegate shortcuts on macOS.
Skills, plugins and MCP
Skills are instruction bundles; plugins are TypeScript packages with lifecycle hooks and can ship their own apps. A marketplace lets you install either from inside the app, plugins can declare MCP servers, and the assistant can write new skills for itself from patterns in its memory.
A permission-first security model
Sensitive actions raise Allow or Deny prompts with a risk badge, trust rules come in Conservative, Relaxed and Autonomous presets, tool calls run in a sandbox, and OAuth tokens sit in a separate credential process so the model never reads them directly. Vellum also warns before you paste something that looks like an API key. The docs are equally direct about the trade-off: your messages still travel to a cloud model provider.
Model choice and hosting choice
The assistant works with Anthropic, OpenAI, Google Gemini, Fireworks, OpenRouter, MiniMax and any OpenAI-compatible endpoint, with local models through Ollama. Run it in Vellum Cloud, or on your own Mac or Windows PC under the MIT license.
Vellum Pricing: Plans, Credits and the Real Monthly Cost
Vellum's docs describe two plans, Base (free) and Pro, with Pro split into three preset packages and a Custom option. Prices below come from the official pricing page and pricing docs as of October 2026.
| Plan | Price / month | Machine | Storage | Included usage & extras |
|---|---|---|---|---|
| Base | $0 | Small (1 vCPU, 2 GiB) | 6 GiB | Pay-as-you-go credits, no monthly minimum, managed model keys |
| Mighty | $30 | Small (1 vCPU, 2 GiB) | 10 GiB | Monthly "Mighty Usage"; no custom subdomain or priority support |
| Super | $100 | Medium (2.5 vCPU, 5 GiB) | 30 GiB | Monthly "Super Usage"; assistant email and subdomain |
| Ultra | $200 | Large (4 vCPU, 8 GiB) | 60 GiB | Monthly "Ultra Usage"; assistant email and subdomain |
| Custom | From $50 | Medium, Large or XL | 10–120 GiB | Pick each component; optional usage bundle at $25, $45 or $115 |
| Self-hosted | $0 platform fee | Your hardware | Your disk | MIT-licensed code; you pay model providers directly |
Here is the arithmetic the pricing page never shows in one place. The published component prices add up exactly to the package prices: Mighty is a $5 storage tier plus a $25 usage bundle, so the "$30 plan" is mostly prepaid usage rather than infrastructure. Super stacks a $10 platform fee, a $35 Medium machine, $10 of storage and a $45 bundle. Ultra is $10 plus $60 plus $15 plus $115. That is our own calculation from Vellum's listed numbers, but it reframes the decision. You are not renting a seat. You are renting a small computer and pre-buying inference.
Beyond the bundle, credits cost $1 each and are spent on model inference, web search, image generation and paid third-party APIs. Included usage resets every billing cycle and does not roll over; purchased credits last twelve months. Top-ups run from $10 to $100, Auto-Reload has an optional monthly cap, and a daily credit limit is available (and required when auto top-ups are on). Vellum says it adds no markup to token costs.
One wrinkle: the pricing docs list the $10 platform fee as included in Super and Ultra, while some Vellum marketing pages phrase it as "plus a $10 platform fee." The docs and the page arithmetic agree with each other, so we treat the package prices as all-in, but confirm at checkout.
The company is unusually candid about the weak spot. In a September 2, 2026 post, Vellum explained that credits describe cost precisely but capability poorly, and that a test pushing free users toward plans instead of top-ups cut credit-purchase revenue by 44% while lifting overall revenue 28% over roughly three and a half weeks. The conclusion was a hybrid model, which is what exists now.
Learning Curve: Minutes to Hatch, Weeks to Trust
Getting a first assistant running is genuinely quick. The docs promise about five minutes from sign-up to a first conversation, and onboarding asks about your work and the personality you want before you meet it.
The slower curve is everything after that. You will correct it, decide which accounts it may touch, choose a trust preset, and, if you care about the invoice, set a daily credit limit and ask it to run heartbeats less often or on a cheaper model. Vellum's own comparison pages admit a short period while it builds context on you. We would give it a couple of weeks of real use before judging it, not an afternoon.
Pros and Cons
Vellum vs Devin vs Lindy
| Vellum | Devin | Lindy | |
|---|---|---|---|
| Core job | Personal assistant with persistent memory | Autonomous software-engineering agent | AI teammate for email, scheduling and Slack requests |
| Free tier | Yes (Base) | Yes, light quota | No free plan reported |
| Paid entry | $30 (Mighty) | $20 (Pro) | $29.99 per user (Plus) |
| Top individual tier | $200 (Ultra) | $200 (Max) | $199.99 per user (Max) |
| How usage is metered | Included monthly usage, then $1 credits | Daily and weekly quotas, extra at API pricing | Pooled monthly credits per seat |
| Open source / self-host | MIT, self-hostable | Proprietary; dedicated deployment on Enterprise | Proprietary |
These three do not really compete head to head, and that is the point. Devin sells delegated engineering work, and its pricing now follows a subscription-with-quotas model rather than the older compute-unit one that many comparison pages still describe, as we noted in our look at what ChatGPT, Claude and Devin really cost. Lindy, covered in our virtual chief-of-staff review, bills per seat with credits pooled across a workspace, per September 2026 third-party pricing breakdowns. Vellum is the only one of the three you can read, fork and run yourself.
If you want tickets turned into pull requests, Vellum is the wrong tool. If you want one assistant to hold your context across Slack, email and your desktop, it is the more ambitious of the three.
What Users Say About the Cost
The commenter goes on to say the rest of the product is strong, and that is the pattern worth noticing: the complaint is about what the meter does to the experience, not about capability. Treat it as a signal rather than a verdict, though. The same analysis points out that organic community discussion of the assistant is still thin, which makes any single comment a small sample.
✅ Choose Vellum if...
You want one persistent assistant across Slack, email, voice and desktop, you value open-source control over your data and keys, and you are comfortable setting spend limits and trust rules.
❌ Look elsewhere if...
You need a coding agent that works through tickets, you require published compliance attestations for the assistant today, you want one flat bill, or you need an always-on assistant on your own server right now.
Expert Editorial Opinion
The most interesting thing about Vellum is not a feature; it is the trajectory. In July 2025 the company announced a $20 million Series A to help teams take AI systems from prototype to production. By January 2026 it was pitching an agent builder for ops teams, and by May it was introducing a Personal Intelligence aimed at individuals. Three audiences in about ten months. You can read that as restlessness or as a team following demand, and either way a buyer should price in the chance that today's product shape is not next year's.
What carries over is discipline. A company with an evaluation-tooling past now publishes detailed memory notes and ships release notes every few days. That is a better sign than polished marketing.
Memory is the real wager. Vellum says its own engineers ship roughly twice as many pull requests per month with an assistant, a number worth noting and not worth leaning on, since it is self-reported, uncontrolled and drawn from a software team. We found no independent benchmark of recall quality. What open source buys you here is the ability to read how consolidation and retrieval actually work instead of trusting a demo, which is more than most memory-first products, including the ones in our memory API roundup, can offer.
Then comes the Pricing Gap, the distance between the number on the card and the number on the invoice. Mighty says $30, but strip out the usage bundle and the infrastructure part is about $5. Everything beyond the allowance comes off a credit balance that also pays for work you never requested: memory consolidation, summaries, heartbeats. Vellum lists those background actions in its own docs and says it is working on making them easier to see. That is honest, though it is not the same as predictable. Per-seat tools such as Lindy also meter by credits, so nobody in this category escapes the question, but software meant to sit quietly in the background should not need a billing dashboard to be understood.
Would we pay $30 for it if the free Base plan did not exist? Not on faith. The free tier and the MIT license are what make Vellum a low-regret experiment, and they are why the score lands where it does. The second price is trust. An assistant with its own inbox, calendar access and computer-use permissions deserves the scrutiny you would give a new hire, a theme we explored in who is watching your company's AI agents. Vellum's permission prompts and credential isolation are the right instincts. They are not a reason to skip the Conservative trust preset on day one.
Final Verdict
At 7.65, Vellum sits in the 7.0–7.9 band: competent but compromised, a good fit for a specific kind of user rather than the majority. It earns its marks for open-source flexibility and a memory design that is documented rather than merely advertised. It loses them to a billing model with background spend that is hard to forecast, pre-1.0 maturity and a short, shifting track record. If you fit the profile in the box above, start on the free Base plan, set a daily credit limit, and try it at vellum.ai before paying for anything.
| Dimension | Weight | Score /10 | Why |
|---|---|---|---|
| Technical quality | 30% | 7.8 | Detailed, credible architecture and sandboxing, but little independent evidence of real-world reliability. |
| Price-to-value | 25% | 7.4 | Free tier and at-cost model pass-through, offset by unpredictable background credit spend. |
| Maturity & documentation | 20% | 6.8 | Excellent docs and release notes, but pre-1.0 software after repeated repositioning. |
| Ceiling & flexibility | 15% | 9.0 | MIT license, bring-your-own-model, local models, plugins and MCP. |
| Honesty of positioning | 10% | 7.5 | Docs admit trade-offs openly, though Vellum's own comparison posts rank Vellum first. |
Weighted score: (7.8 × 0.30) + (7.4 × 0.25) + (6.8 × 0.20) + (9.0 × 0.15) + (7.5 × 0.10) = 2.34 + 1.85 + 1.36 + 1.35 + 0.75 = 7.65.
❓ Frequently Asked Questions
🔗 Related ToolRadar Reviews
Official website: vellum.ai · Open-source repository: github.com/vellum-ai/vellum-assistant
Comments
Post a Comment